

There’s a specific moment I keep hitting with every agent I’ve tested this year.
It’s not the moment it does something impressive. That comes early and it’s cheap. It’s the moment about forty minutes later, when the agent is four tabs deep into a real tool with a real login, and I realise I can’t answer a simple question: if this goes wrong, whose name is on it?
Not “will it go wrong.” Whose name.
Grok Bot is the product that made that question urgent for me, because it answers it the most aggressively of anything shipping right now. It works on a computer you don’t own, holding sessions you signed into, under your name.
So this is a Grok Bot piece first. But I can’t evaluate it in isolation, because the comparison everyone is posting is broken in a way that matters, and fixing it is most of the analysis.
Here’s the fix: Hermes Agent and OpenClaw are not competitors to Grok Bot. They’re not even the same kind of object.
They are harnesses. A gateway, a memory layer, a skills system, a scheduler, sandboxing, and a socket where you plug in whichever model you want. Model-agnostic by design. You assemble the agent; the harness is the scaffolding you assemble it on.
Grok Bot and Claude Cowork are products. Model, harness, hosting, billing and support arrive welded together. Grok Bot doesn’t even give you a model picker: routing is fully product-managed, with automatic failover, and billing follows whichever model actually served the request.
That’s a buy decision versus a build decision, and they fail differently. When a product breaks, you file a ticket. When a harness breaks, you are the ticket.
Once you separate those, the real axis shows up. It isn’t capability. All four read email, drive browsers, remember last week and run on schedules; the feature grids are nearly interchangeable. The axis is custody: whose machine the work happens on, whose credentials it uses, and who can prove afterwards what it did.
Let’s use that.
What Grok Bot actually is
Grok Bot shipped on 11 August 2026 in early beta. It’s documented at x.ai/bot and docs.x.ai/grok-bot.
First correction, because I’ve seen this wrong in about nine posts already: it is not built by X Corp. The maker is SpaceXAI (SpaceX merged with xAI in February 2026). The iOS app publisher is Anysphere, Cursor’s legal name, because SpaceX’s $60B acquisition of Anysphere became effective around 14 August. Which means for three days xAI was selling a product built by a company it did not yet own. That’s not a scandal. It is a useful reminder of how fast this thing was assembled.
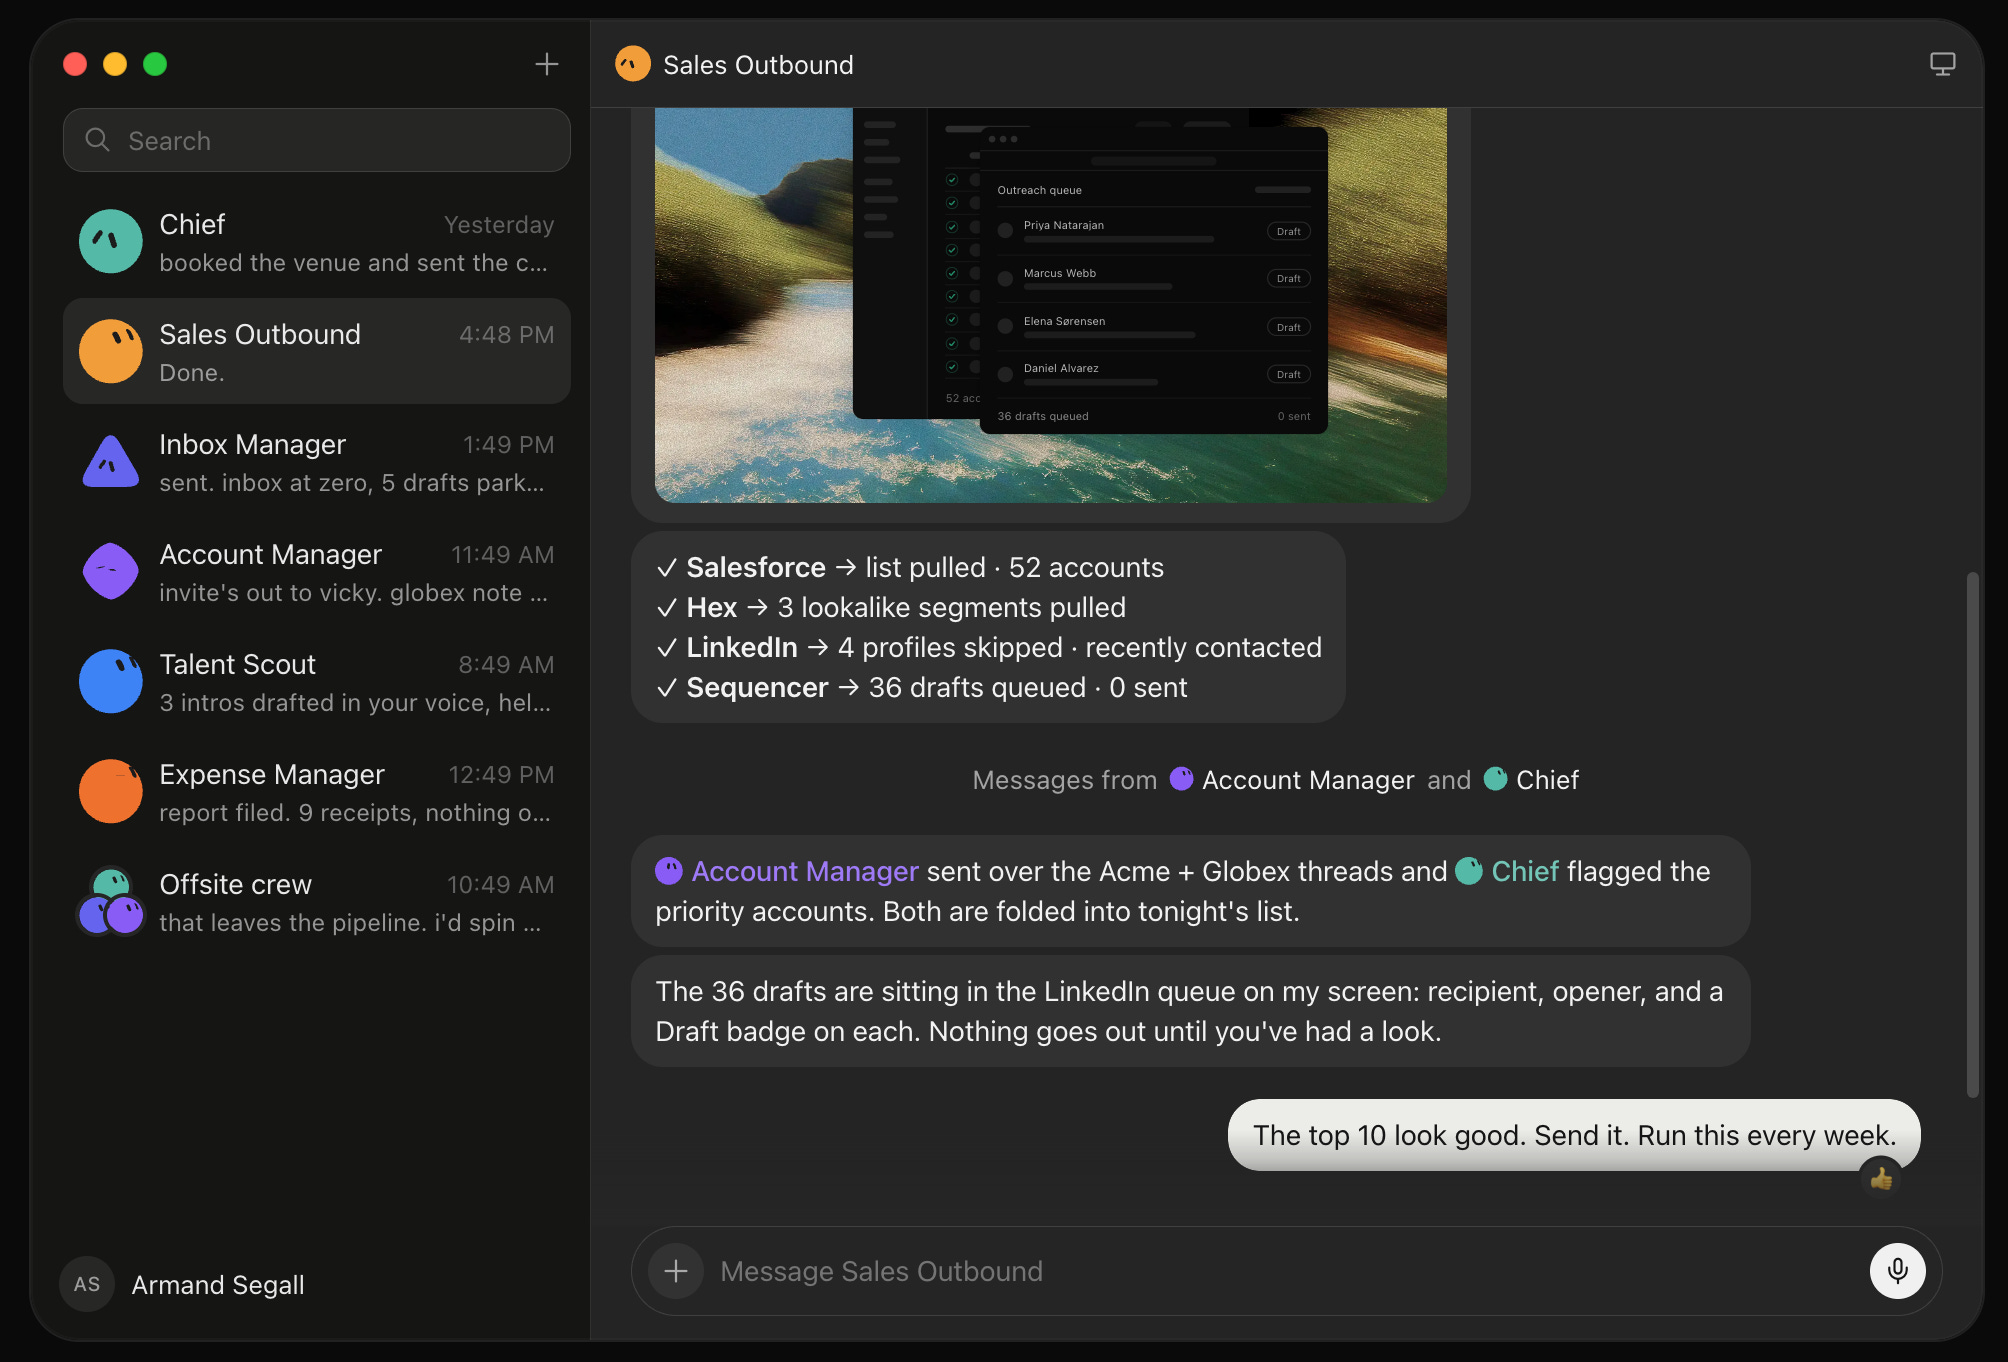
The pitch is “an AI teammate.” The reality is more specific, and more interesting:
A cloud computer. Grok Bot works on a managed Linux VM running in SpaceXAI’s cloud. It drives a browser. It logs into real apps with real sessions.
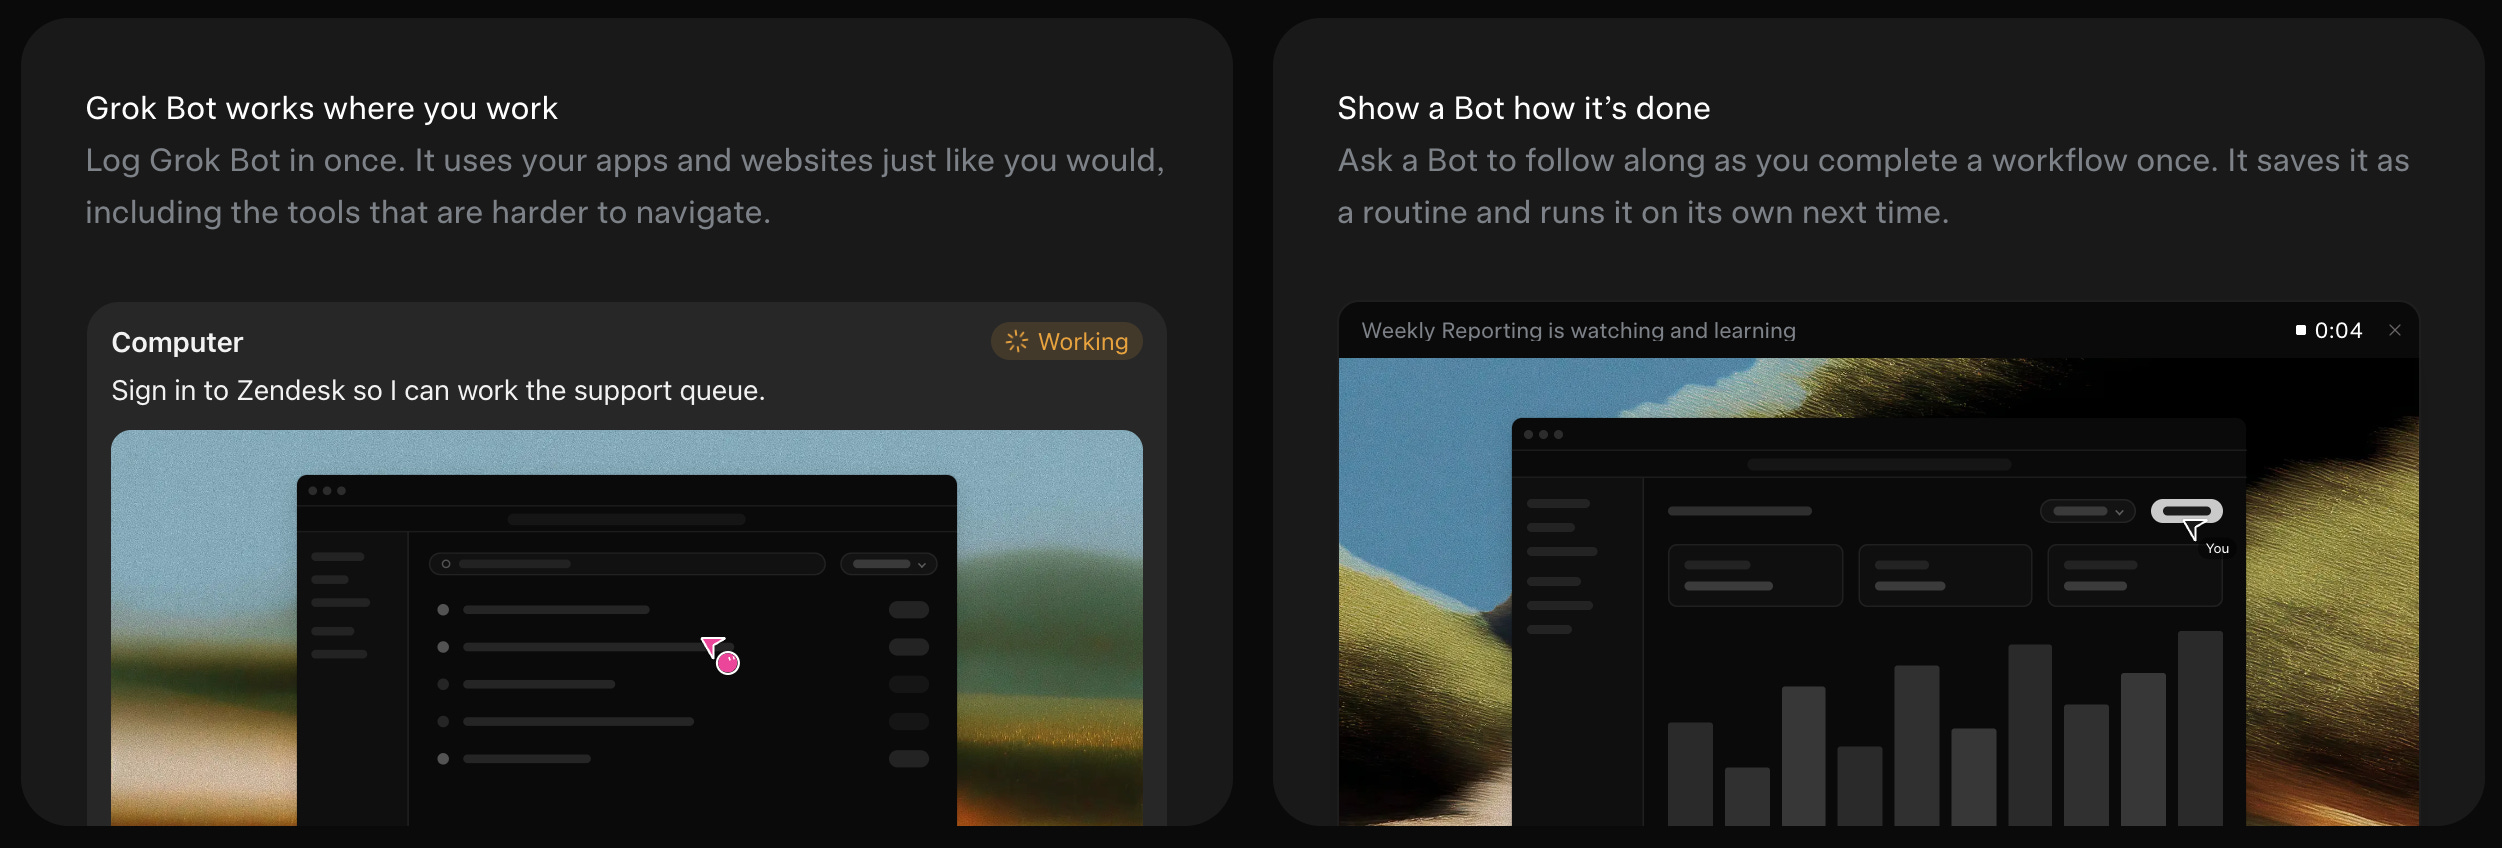
Bots, skills, routines. A skill is how to do something. A routine is when: on a schedule, or on a narrow set of events (the docs name a Slack message and a GitHub notification). Teach a task lets you record a browser workflow, ten minutes maximum, no audio, which produces a draft skill you still have to write rules for.
Approvals. Require Approval rules always stop a matching action. Always Allow proceeds only if the automated review finds nothing else wrong. When both match, Require Approval wins.
Takeover instead of credential handover. This corrects the most common criticism I’ve read. You don’t give the model your password. On a password, passkey, 2FA prompt, CAPTCHA or payment confirmation, the Bot stops and hands you the screen. You complete that step and hand control back.
Plugins, not a catalog. In-app they’re under Settings, and they’re pulled dynamically from the Cursor Marketplace, plus bring-your-own remote MCP. There is no fixed xAI-published connector list. Figma and Vercel plugins are both there per community tracking of the official marketplace, and even without them the Bot can operate either product in the browser.
No model picker, as above. One correction while we’re here: Grok 4.6 is listed on x.ai/bot as a SuperGrok chat feature, separately from Bot access. Nobody has documented it as the Bot runtime. Don’t repeat that claim.
Pricing, all figures 29 August 2026, monthly, annual roughly 20% cheaper. There’s no standalone Grok Bot SKU and no free tier. As of 26 August it’s bundled with all eight plans:
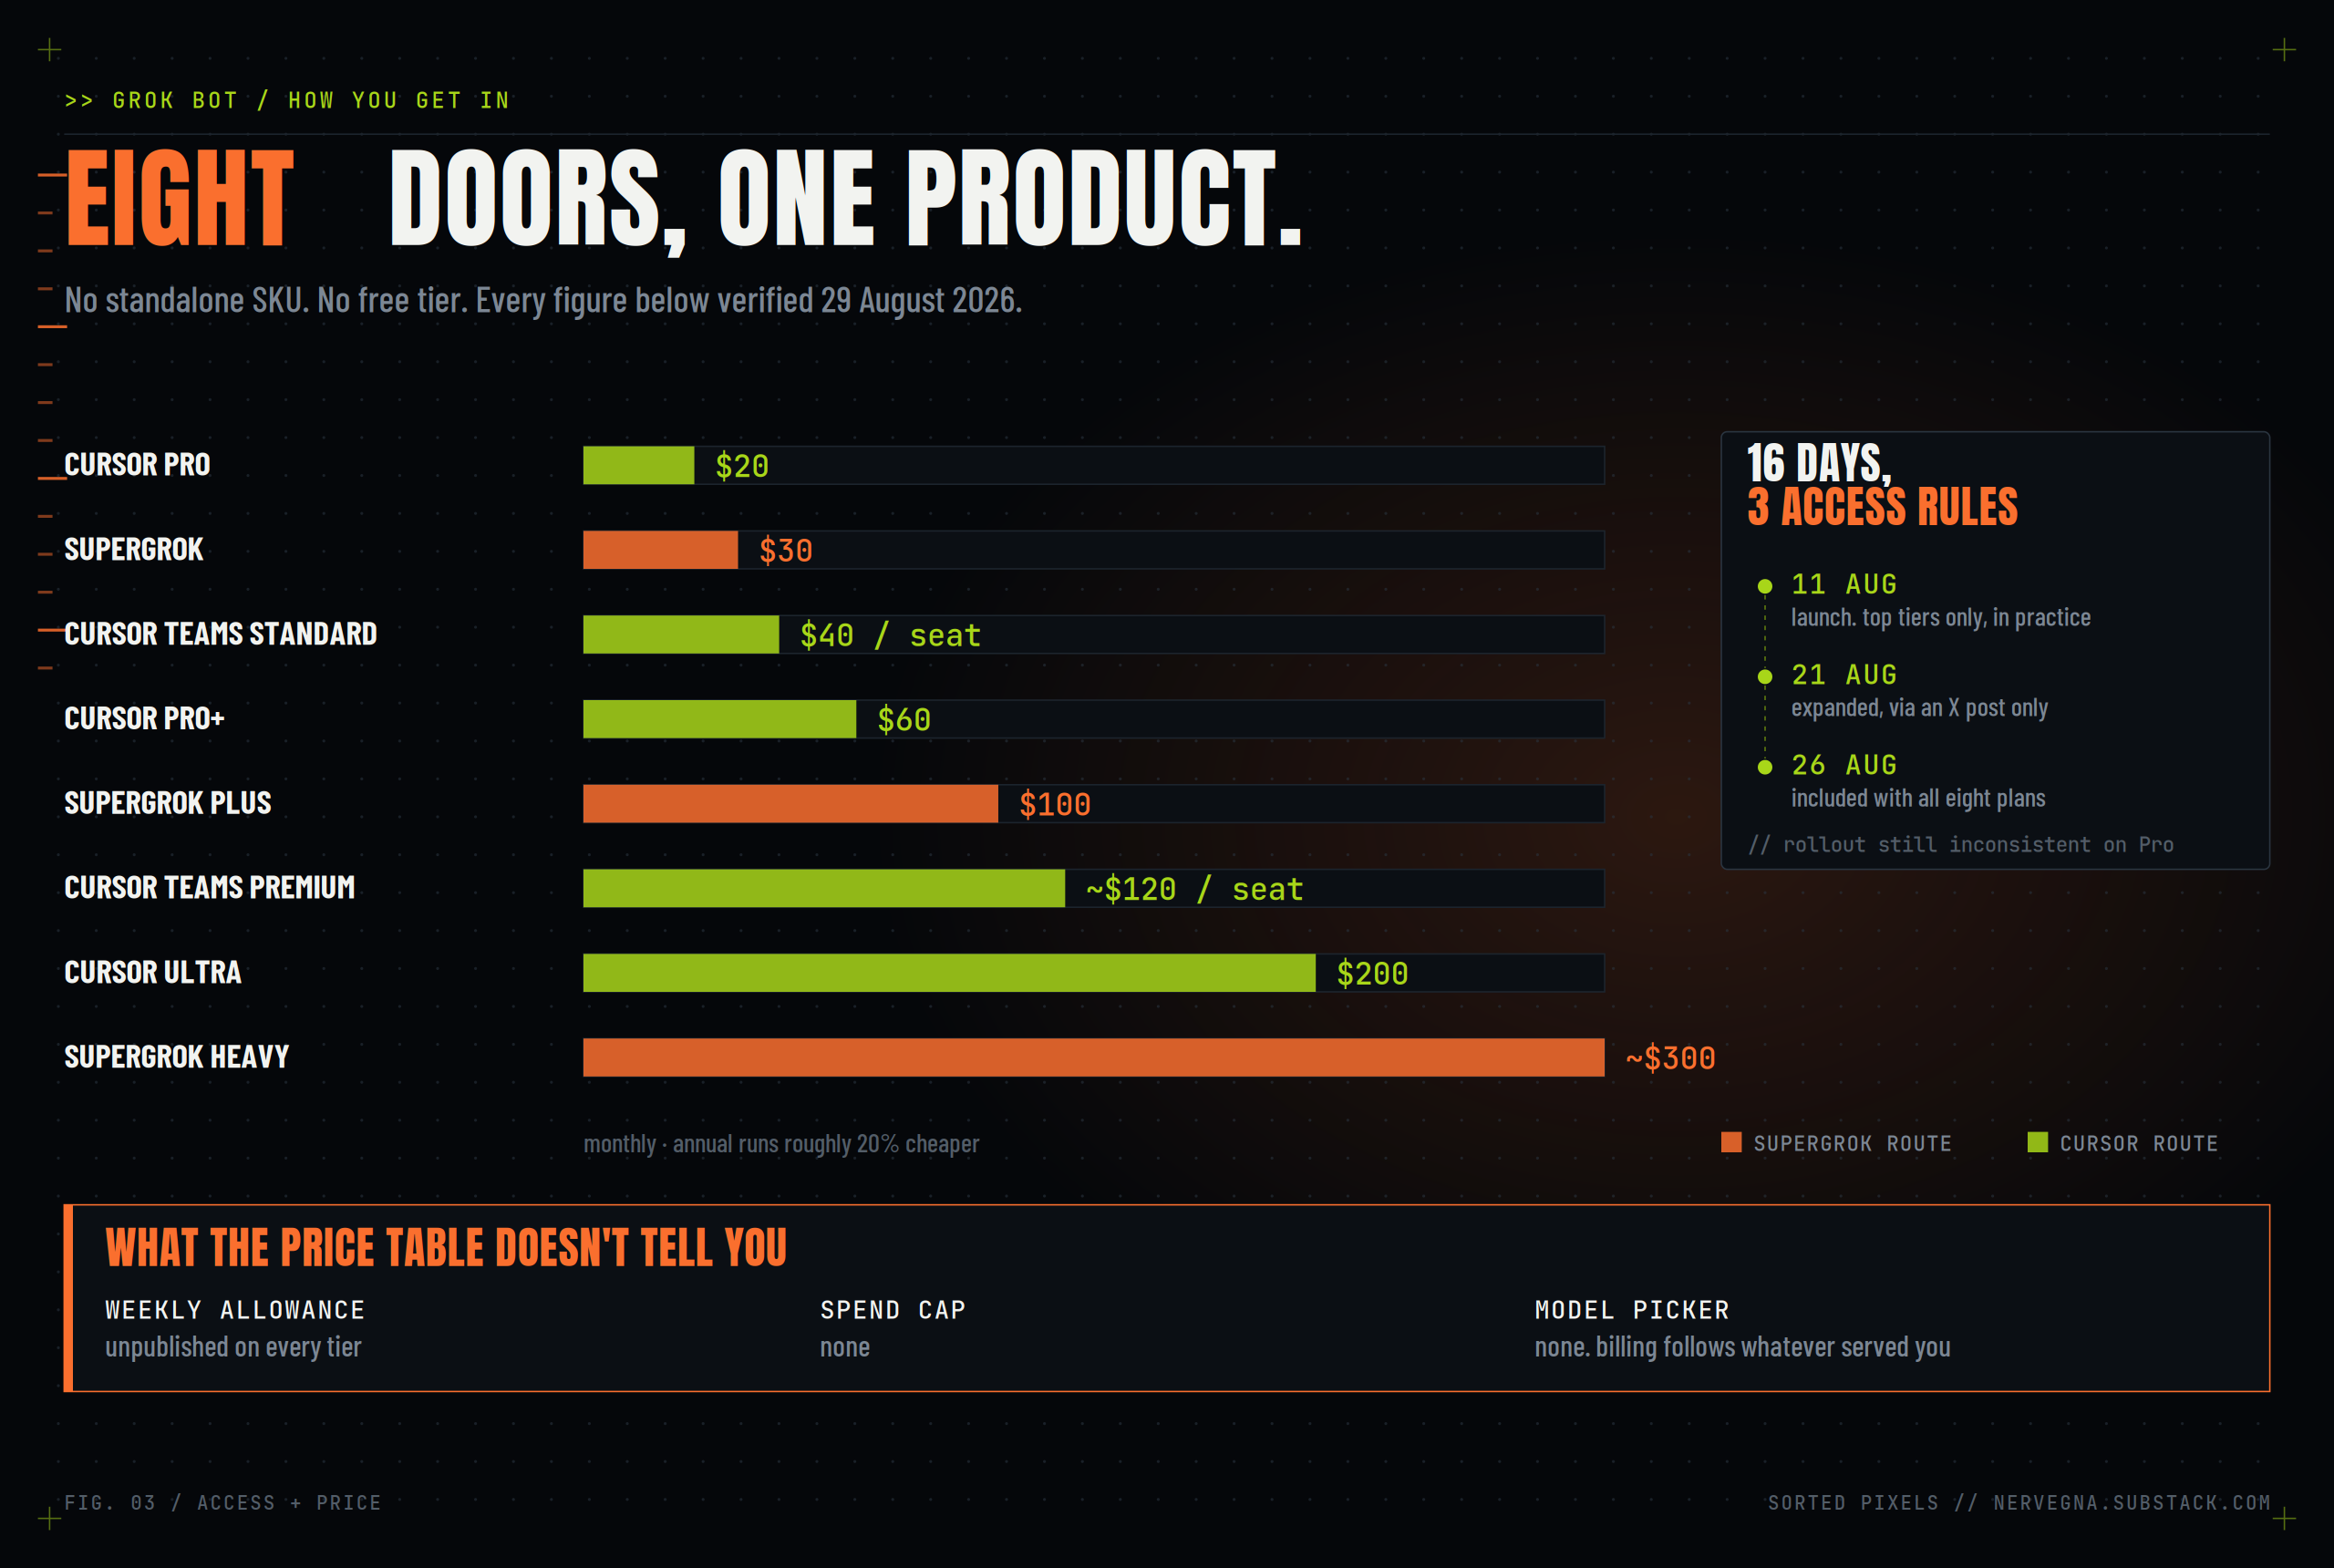
The cheapest door is Cursor Pro at $20. The most expensive is SuperGrok Heavy at around $300. Cursor Teams Standard sits at $40 a seat and Teams Premium at roughly $120 a seat, which is worth a second look: the team plan is cheaper per seat than the $200 solo Ultra plan, which is backwards from how SaaS usually prices.
Each plan includes a weekly Grok Bot allowance whose size is not published on any tier. Past it, you’re billed on model and token cost, with no Grok Bot spend cap and no model picker to steer yourself somewhere cheaper. Hold that thought.
The one diagram that explains everything
The launch page says Bots have their own computer. The docs say all of your Bots share one. The docs are right, and the difference is the whole security story:
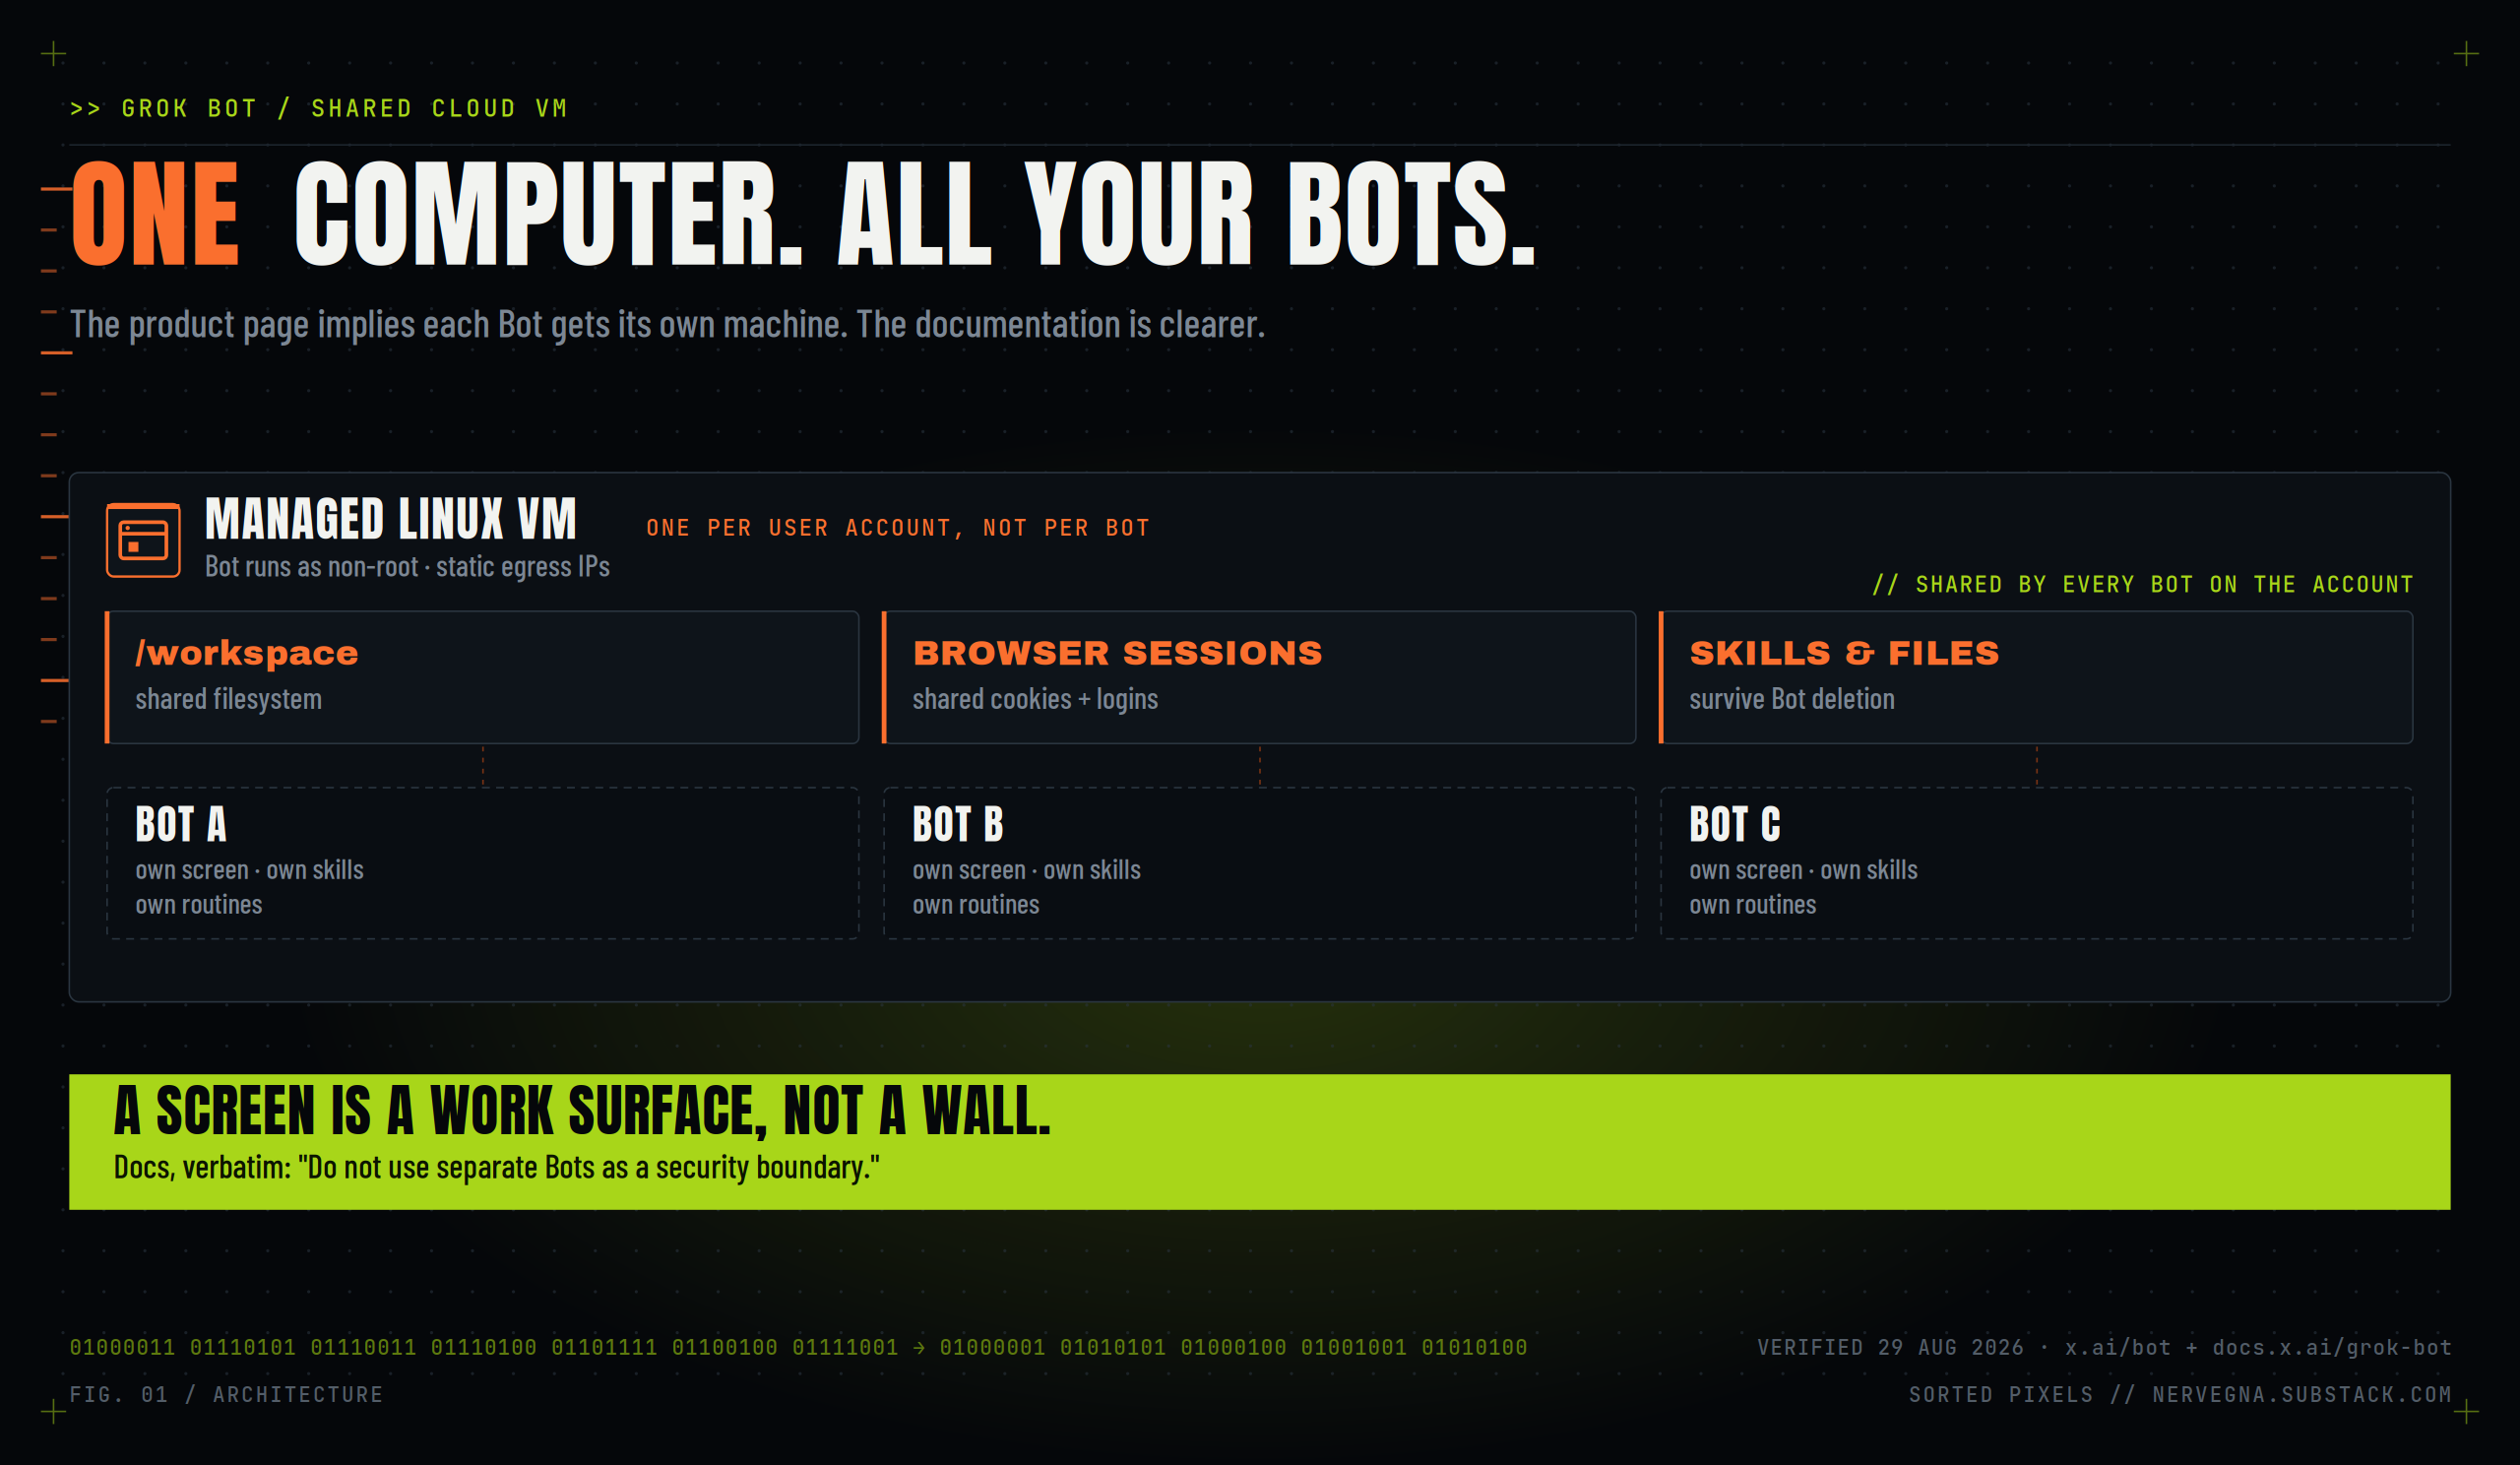
Each Bot gets its own screen. A screen is a work surface. It is not a wall. The documentation says it about as plainly as documentation ever says anything: “Do not use separate Bots as a security boundary.”
I have already run this experiment
Here is the part I can speak to first-hand, because I built the thing Grok Bot is describing and I built it the wrong way first.
Before I moved to isolated agents, I tried running several agents in one shared context. It was chaos. They bled into each other’s tasks, the context got polluted, and the quality of every individual agent dropped. Not catastrophically, which is the dangerous part. Just steadily. The fix was isolation: separate workspace, separate memory, separate schedule per agent. That single change is what turned a toy into something I still use six months later.
I gave my OpenClaw Agent an Org Chart and promoted her to COO. Here's what Happened.

Fair warning: this article contains Final Fantasy VII references, an AI agent named after a flower girl, and the kind of org chart only a lifelong gamer would build. If you ever wondered how deep the nerd goes, now you know.
Grok Bot ships the same configuration, but in a far more user friendlier manner.
Now, be fair to it: separate screens are not the same as a shared context window, and the Bots do get their own skills and routines. This is a weaker version of the problem, not the identical one. But the shared filesystem and the shared browser session are exactly the surfaces where bleed happened for me. Agent A leaves a file in the workspace. Agent B reads it as fact. Agent A logs into a client tenant. Agent B inherits the session.
This is the point I’d push hardest, because it’s the one the security framing misses. The shared computer is not only an audit problem. It’s a quality problem. You will notice the audit gap during an incident, which may never come. You’ll feel the quality drift in week three, when the outputs are slightly worse and you can’t say why.
Fifty Bots on one machine is not fifty specialists. It’s fifty processes sharing a desk.
So the mental model most people are building, “I’ll give the client-facing Bot access to the client stuff and keep my internal Bot separate,” is wrong on day one. One VM. One cookie jar. Everything your Bots can reach, all of your Bots can reach.
Also worth knowing before you demo this to anyone: deleting a Bot removes its profile, conversation and routines, but files and logins on the shared computer can survive. Teardown is a manual checklist, including signing out of sites yourself. And a “test run” does real work. It navigates real sites, changes real files, calls real tools. It is not a dry run.
The one real competitor, and the two harnesses
Now put the others next to it, in the right categories.
The competitor
Claude Cowork with Dispatch is the only thing on this list that Grok Bot is genuinely up against: a finished product, sold by the model vendor, aimed at the same buyer. Cowork launched as a desktop research preview in January, Dispatch (task it from your phone, come back to finished work) on 17 March, computer use a week later. Then it stopped being desktop-only. Since July, sessions and files are cloud-hosted on Anthropic’s infrastructure and scheduled tasks run server-side with no device online. Since 12 August the Claude in Chrome side panel is a full Cowork session carrying your skills and connectors into a browser where you’re already logged in. Remote execution in isolated cloud sandboxes is the default, with no outside network access unless an admin allowlists it. Local execution runs in a VM on your own hardware.
The architectural bet is the mirror image of Grok Bot’s. Cowork’s default is an isolated sandbox that reaches out through permissions you grant. Grok Bot’s default is a persistent computer that’s already inside, logged in as you.
The harnesses
These two belong in the conversation, but not in the same column, and I’ve watched a dozen posts this month put them there anyway.
Hermes Agent (Nous Research) is the harness that grew up. MIT licensed, free, native app for macOS 12+ and Windows 10/11, terminal install on any Linux distro. Its identity is a persistent memory that follows you across Telegram, Discord, Slack, WhatsApp, Signal, email and CLI. One memory, every surface. It auto-generates skills from how it solved things before, spawns isolated subagents with their own terminals, and runs five sandbox backends (local, Docker, SSH, Singularity, Modal). Paid Nous Portal tiers add monthly credits and access to 300+ models.
OpenClaw is the harness the whole category descends from, and still the most-starred thing in it, north of 360k GitHub stars by May 2026. Self-hosted gateway on your hardware or a VPS, messaging apps as the control surface, a heartbeat daemon for scheduled work, and ClawHub as the skills registry. It also has the longest scar tissue: a 40+ vulnerability security release in February, pluggable sandboxes and 20 more patches in March, then ClawScan and an NVIDIA skill-screening partnership in June after the supply-chain mess. That history is a feature. It means someone has already found the holes and written them down.
I should declare an interest here. I’ve been running an OpenClaw org chart since February and migrated to Hermes fully in the last 3 months: eight specialised agents on a Mac mini that hasn’t been turned off since, each with its own workspace, its own memory, its own cron jobs, all routed through a single Telegram thread. Claude models underneath. That last detail is the harness distinction in one sentence. The harness didn’t come with a model. I chose one.
Worth noticing which direction the influence ran, too. Anthropic shipped Cowork, then Dispatch, then computer use in the months after OpenClaw went viral, and the connection has been made openly in the coverage. The harnesses proved the behaviour. The products are productising it.
So read the table below as two comparisons stacked on top of each other: Grok Bot against Cowork, and both against what you’d have to build yourself.
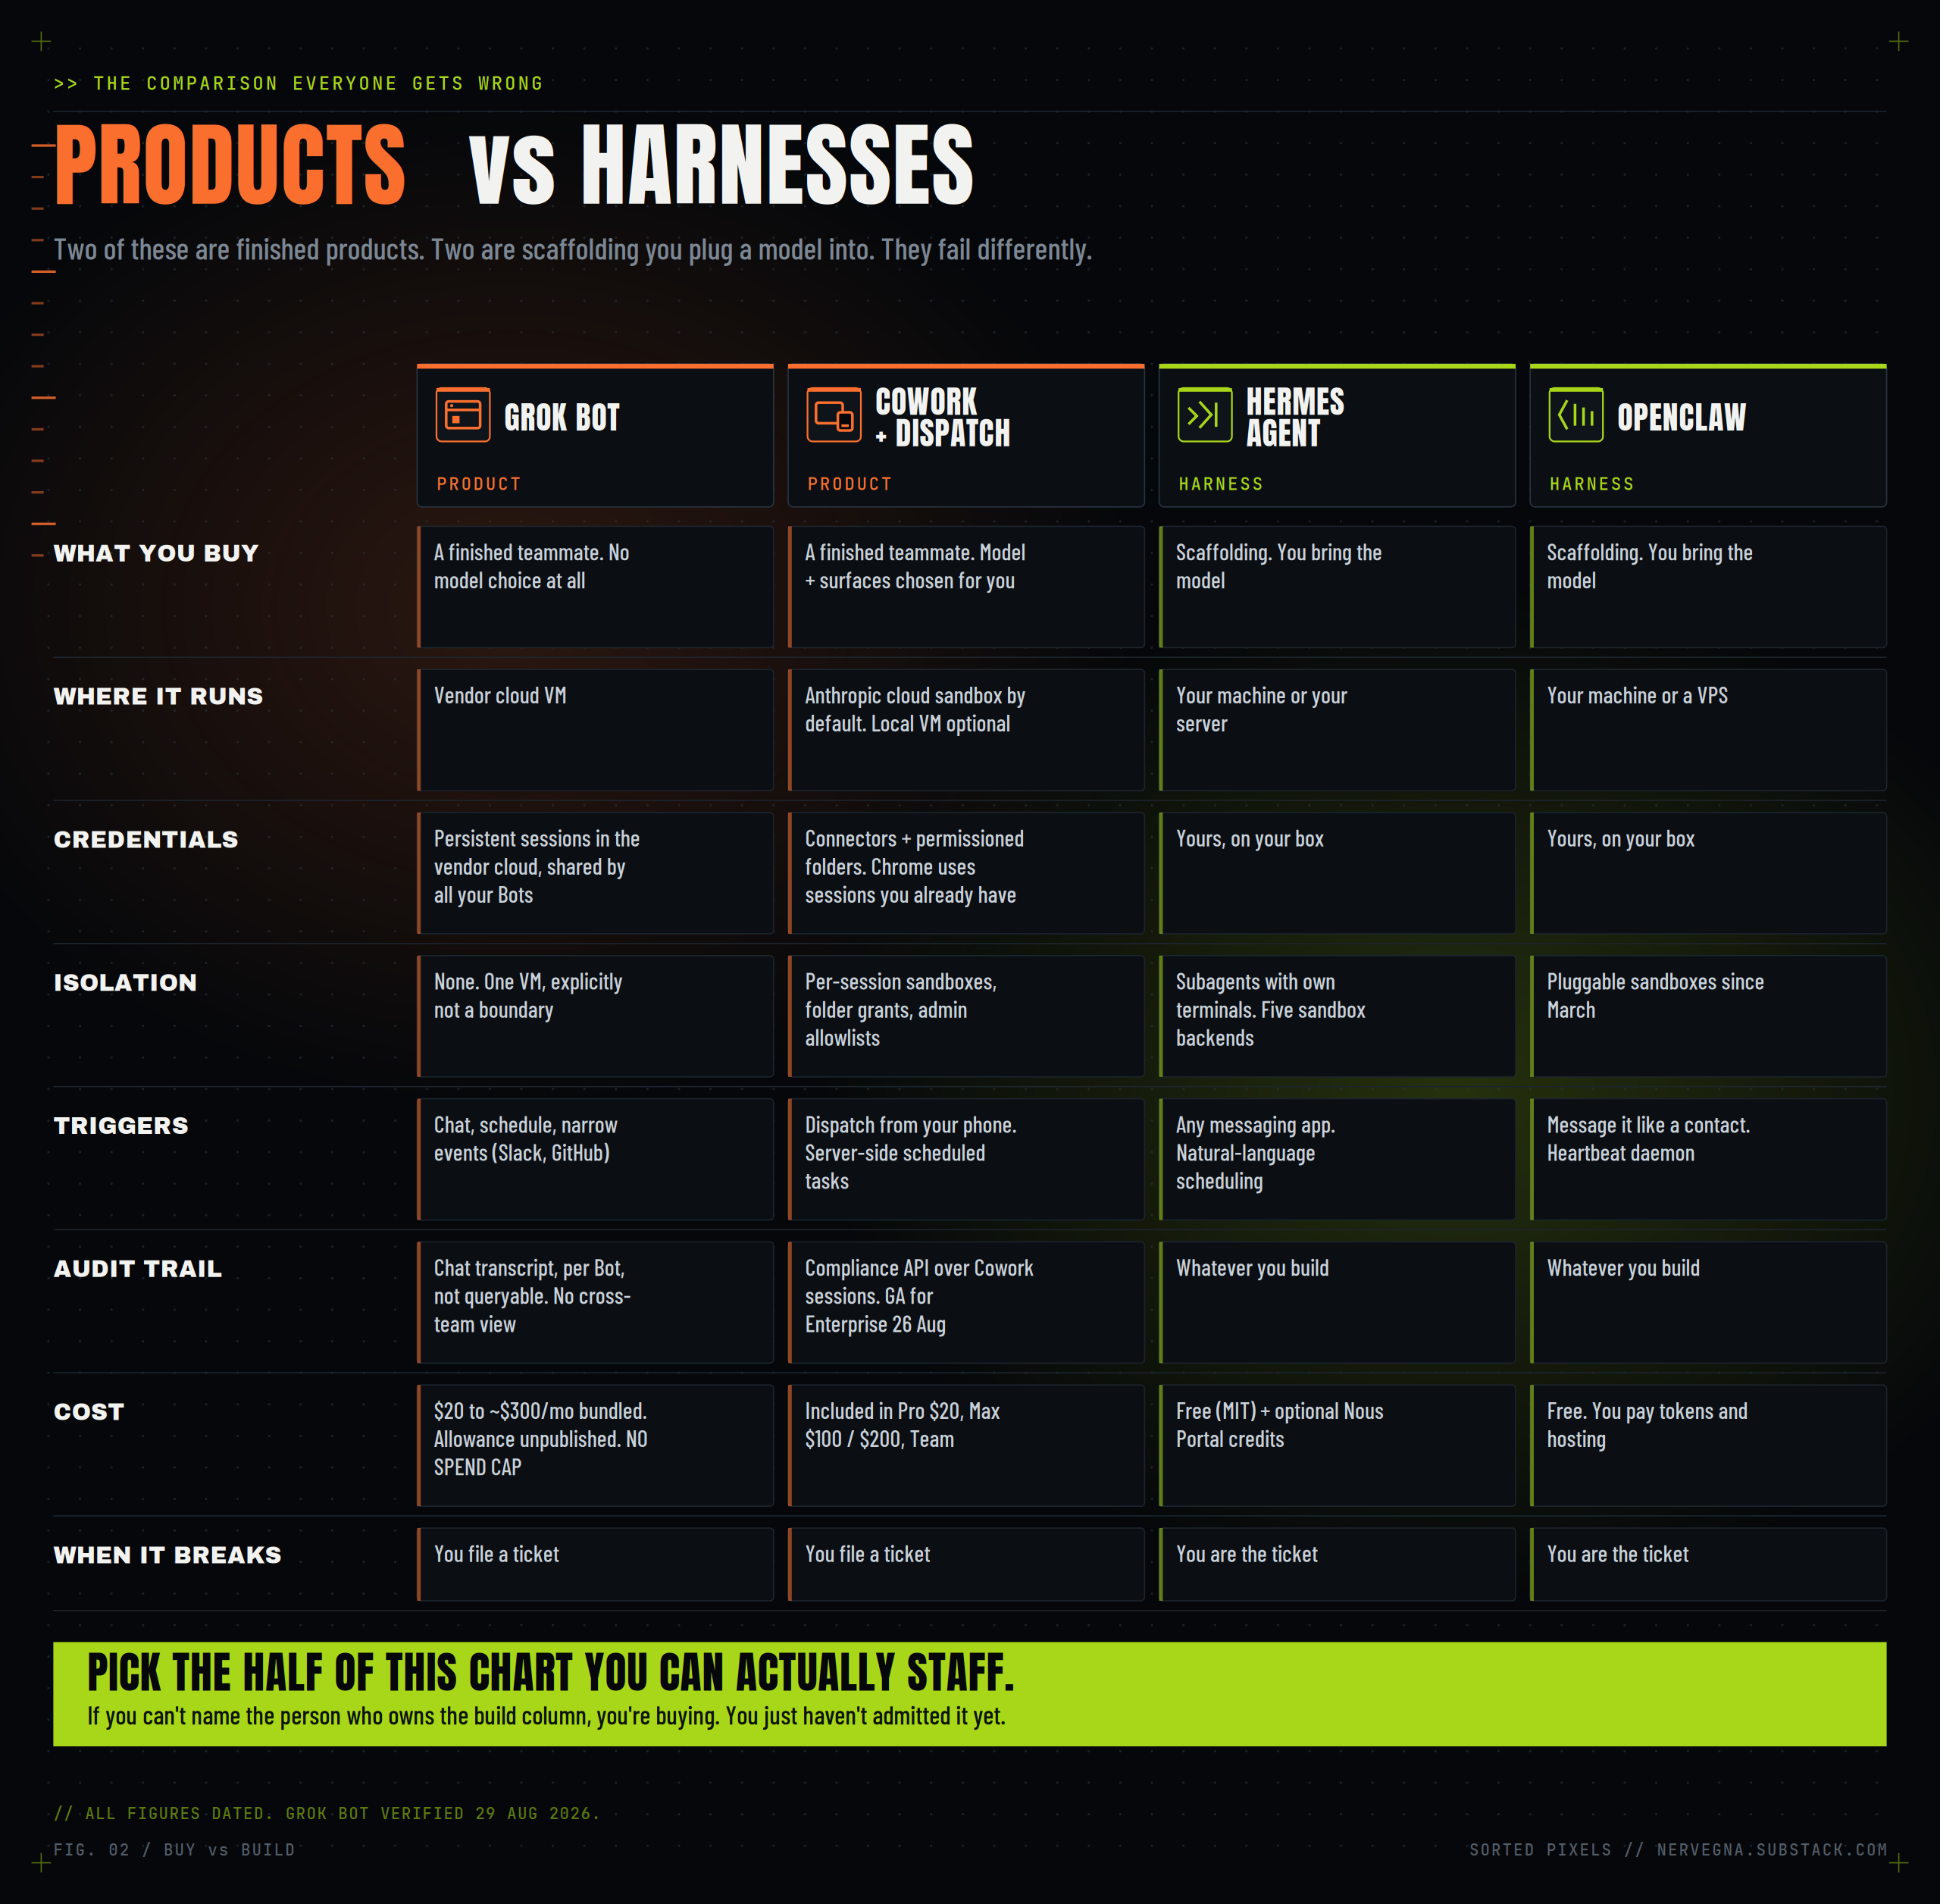
If you only take one row away, take the last one. When a product breaks you file a ticket. When a harness breaks, you are the ticket.
Read that table one more time and notice what it’s actually saying.
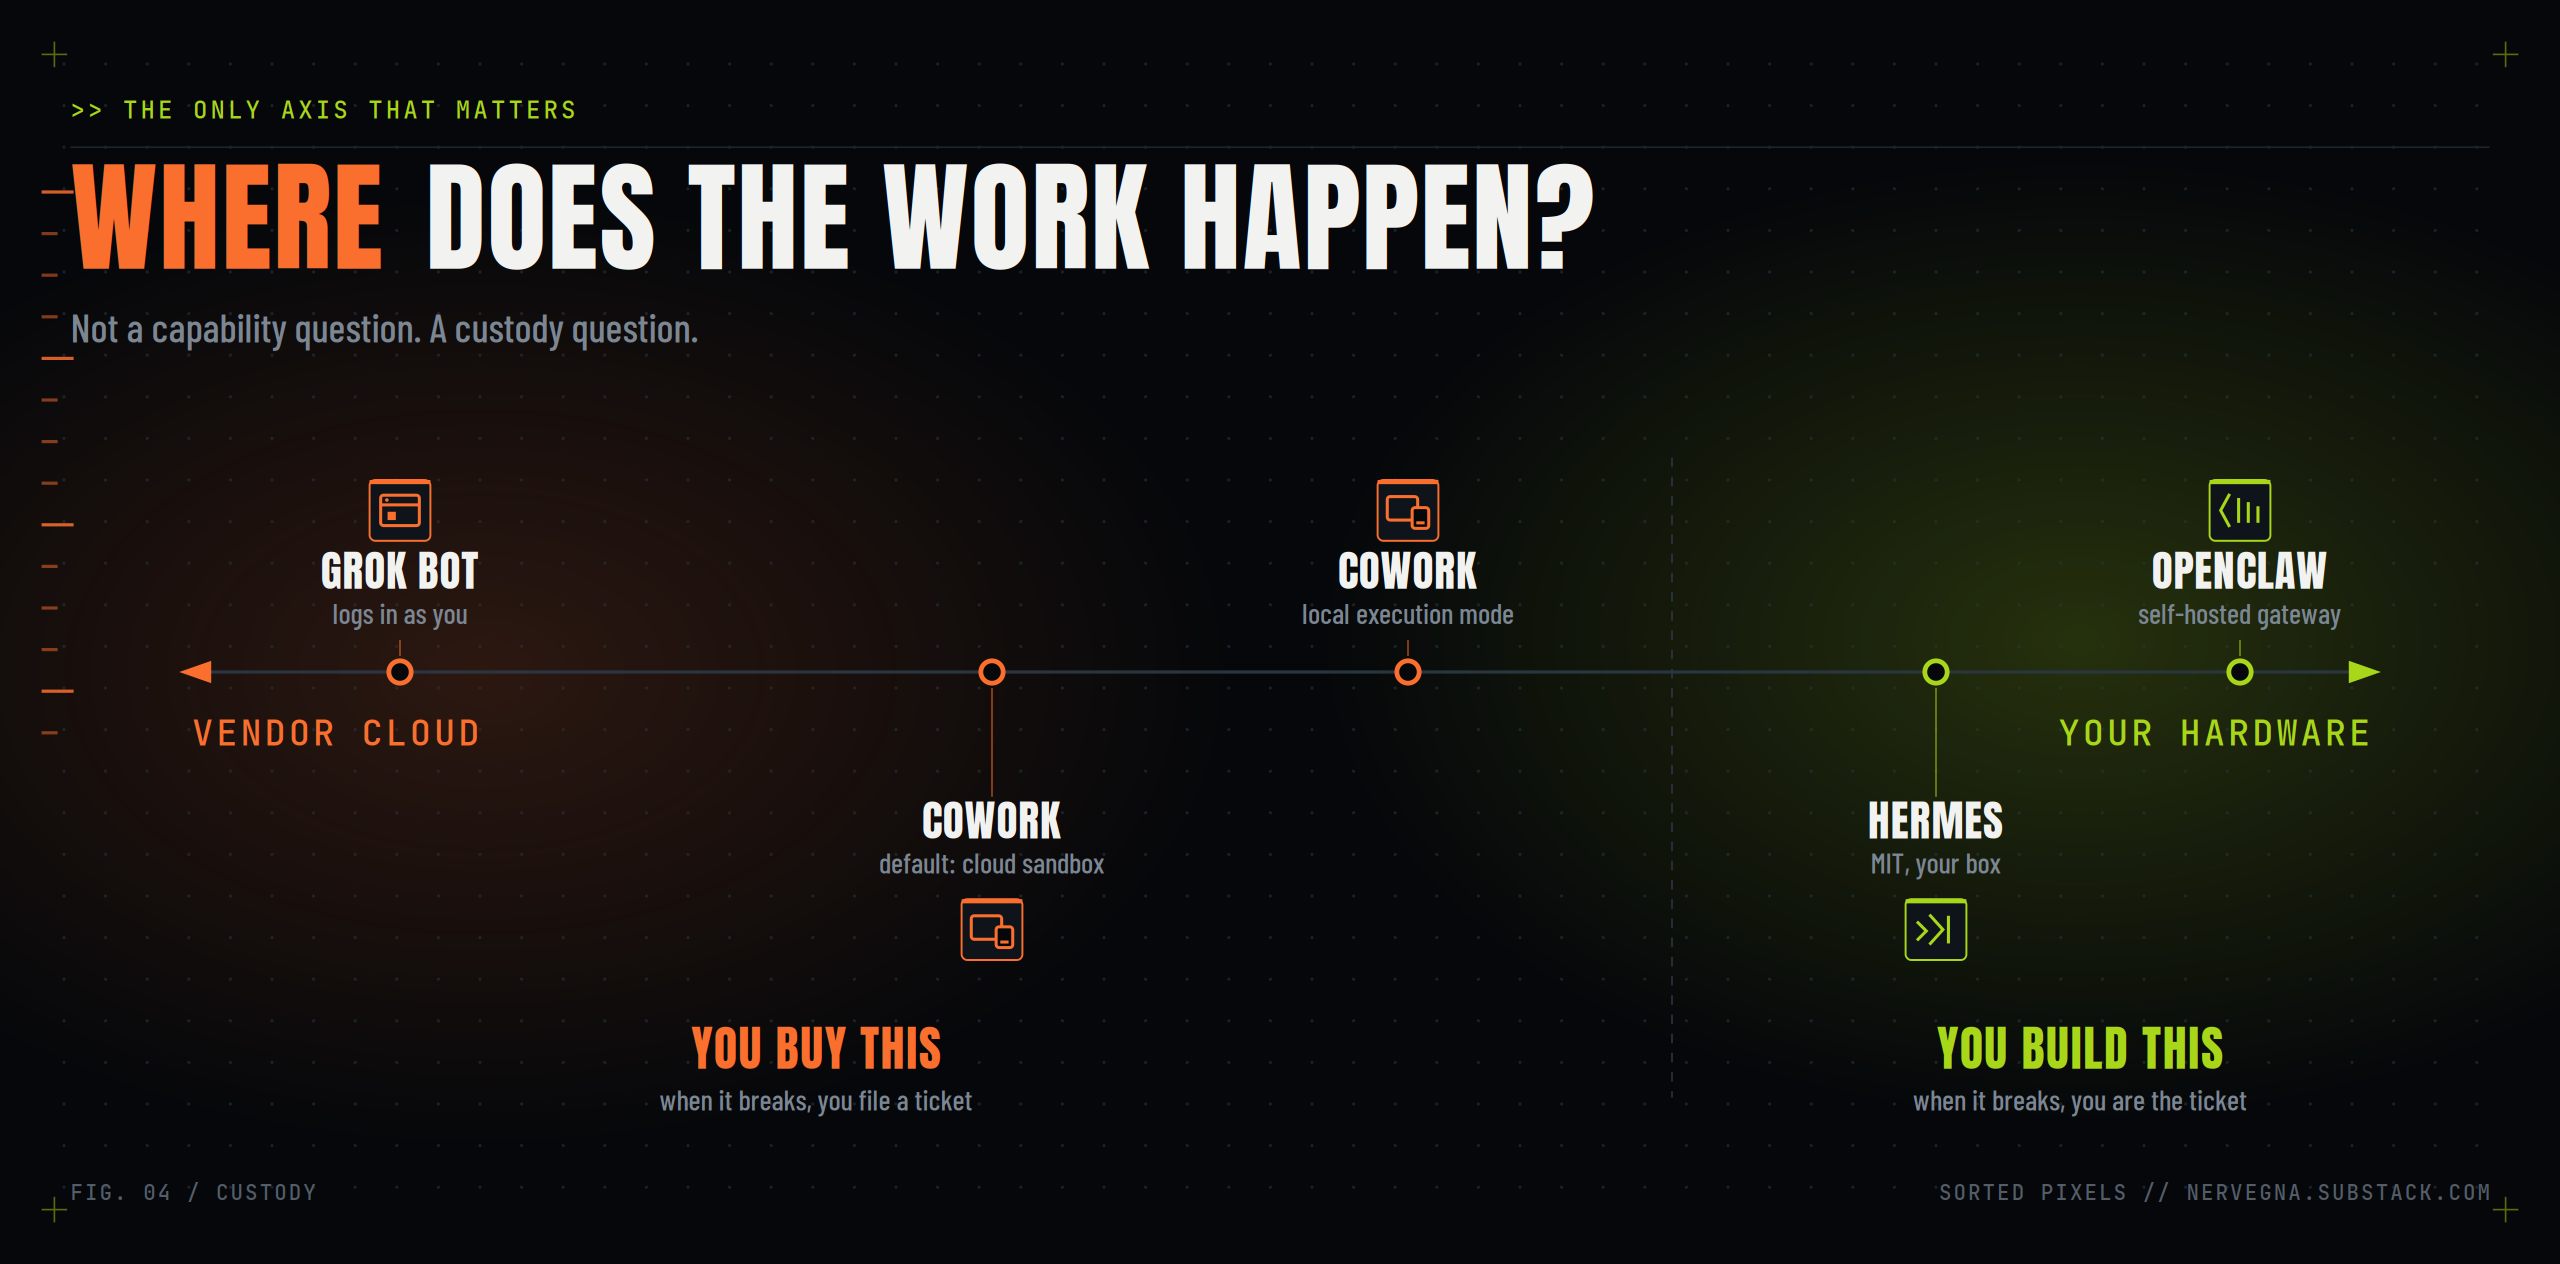
Grok Bot bought the most convenience by giving up the most custody. The harnesses trade the opposite way, and charge you in maintenance instead of money. Cowork sits in the middle by choice: you pick per session, and it’s the only one of the four that currently answers “who can prove what it did” with a product rather than a shrug.
If you’re deciding, don’t start with the feature list. Start with which of those two halves of the diagram your team can actually staff.
What’s genuinely new, and what’s repackaged
Let me be fair to Grok Bot, because the skeptical take is lazy.
Repackaged: computer use, persistent memory, multi-agent, scheduled runs. All of it exists elsewhere. One advocate put it well after a week with the product: nothing it does is impossible in other stacks, what changed is that the user experience unhobbles those use cases. That’s an honest read.
Genuinely new: a persistent, credentialed, always-on cloud teammate that logs in as you and drives apps that never shipped an API or an MCP server. Zapier and n8n need an integration. Grok Bot needs a login screen and a mouse. If your CX team spends nine hours a week inside four vendor portals from 2011, that is not a small thing.
The counter-case is the one I keep coming back to, and someone on r/AI_Agents put it more sharply than I would have: the hard parts are identity, approvals, and audit logs, and without those it’s a browser with chaos privileges rather than an employee.
What this means for you
If you’re a product designer
The highest-value use is not generation. It’s verification nobody schedules.
A bug reproduction agent that recreates an issue in the real UI, writes it up cleanly, and hands engineering something they don’t have to interrogate. A docs-freshness agent that diffs the help centre against what actually shipped and flags the stale pages. A demo-readiness agent that fixes broken seed data overnight so your 9am client call doesn’t open on an empty state.
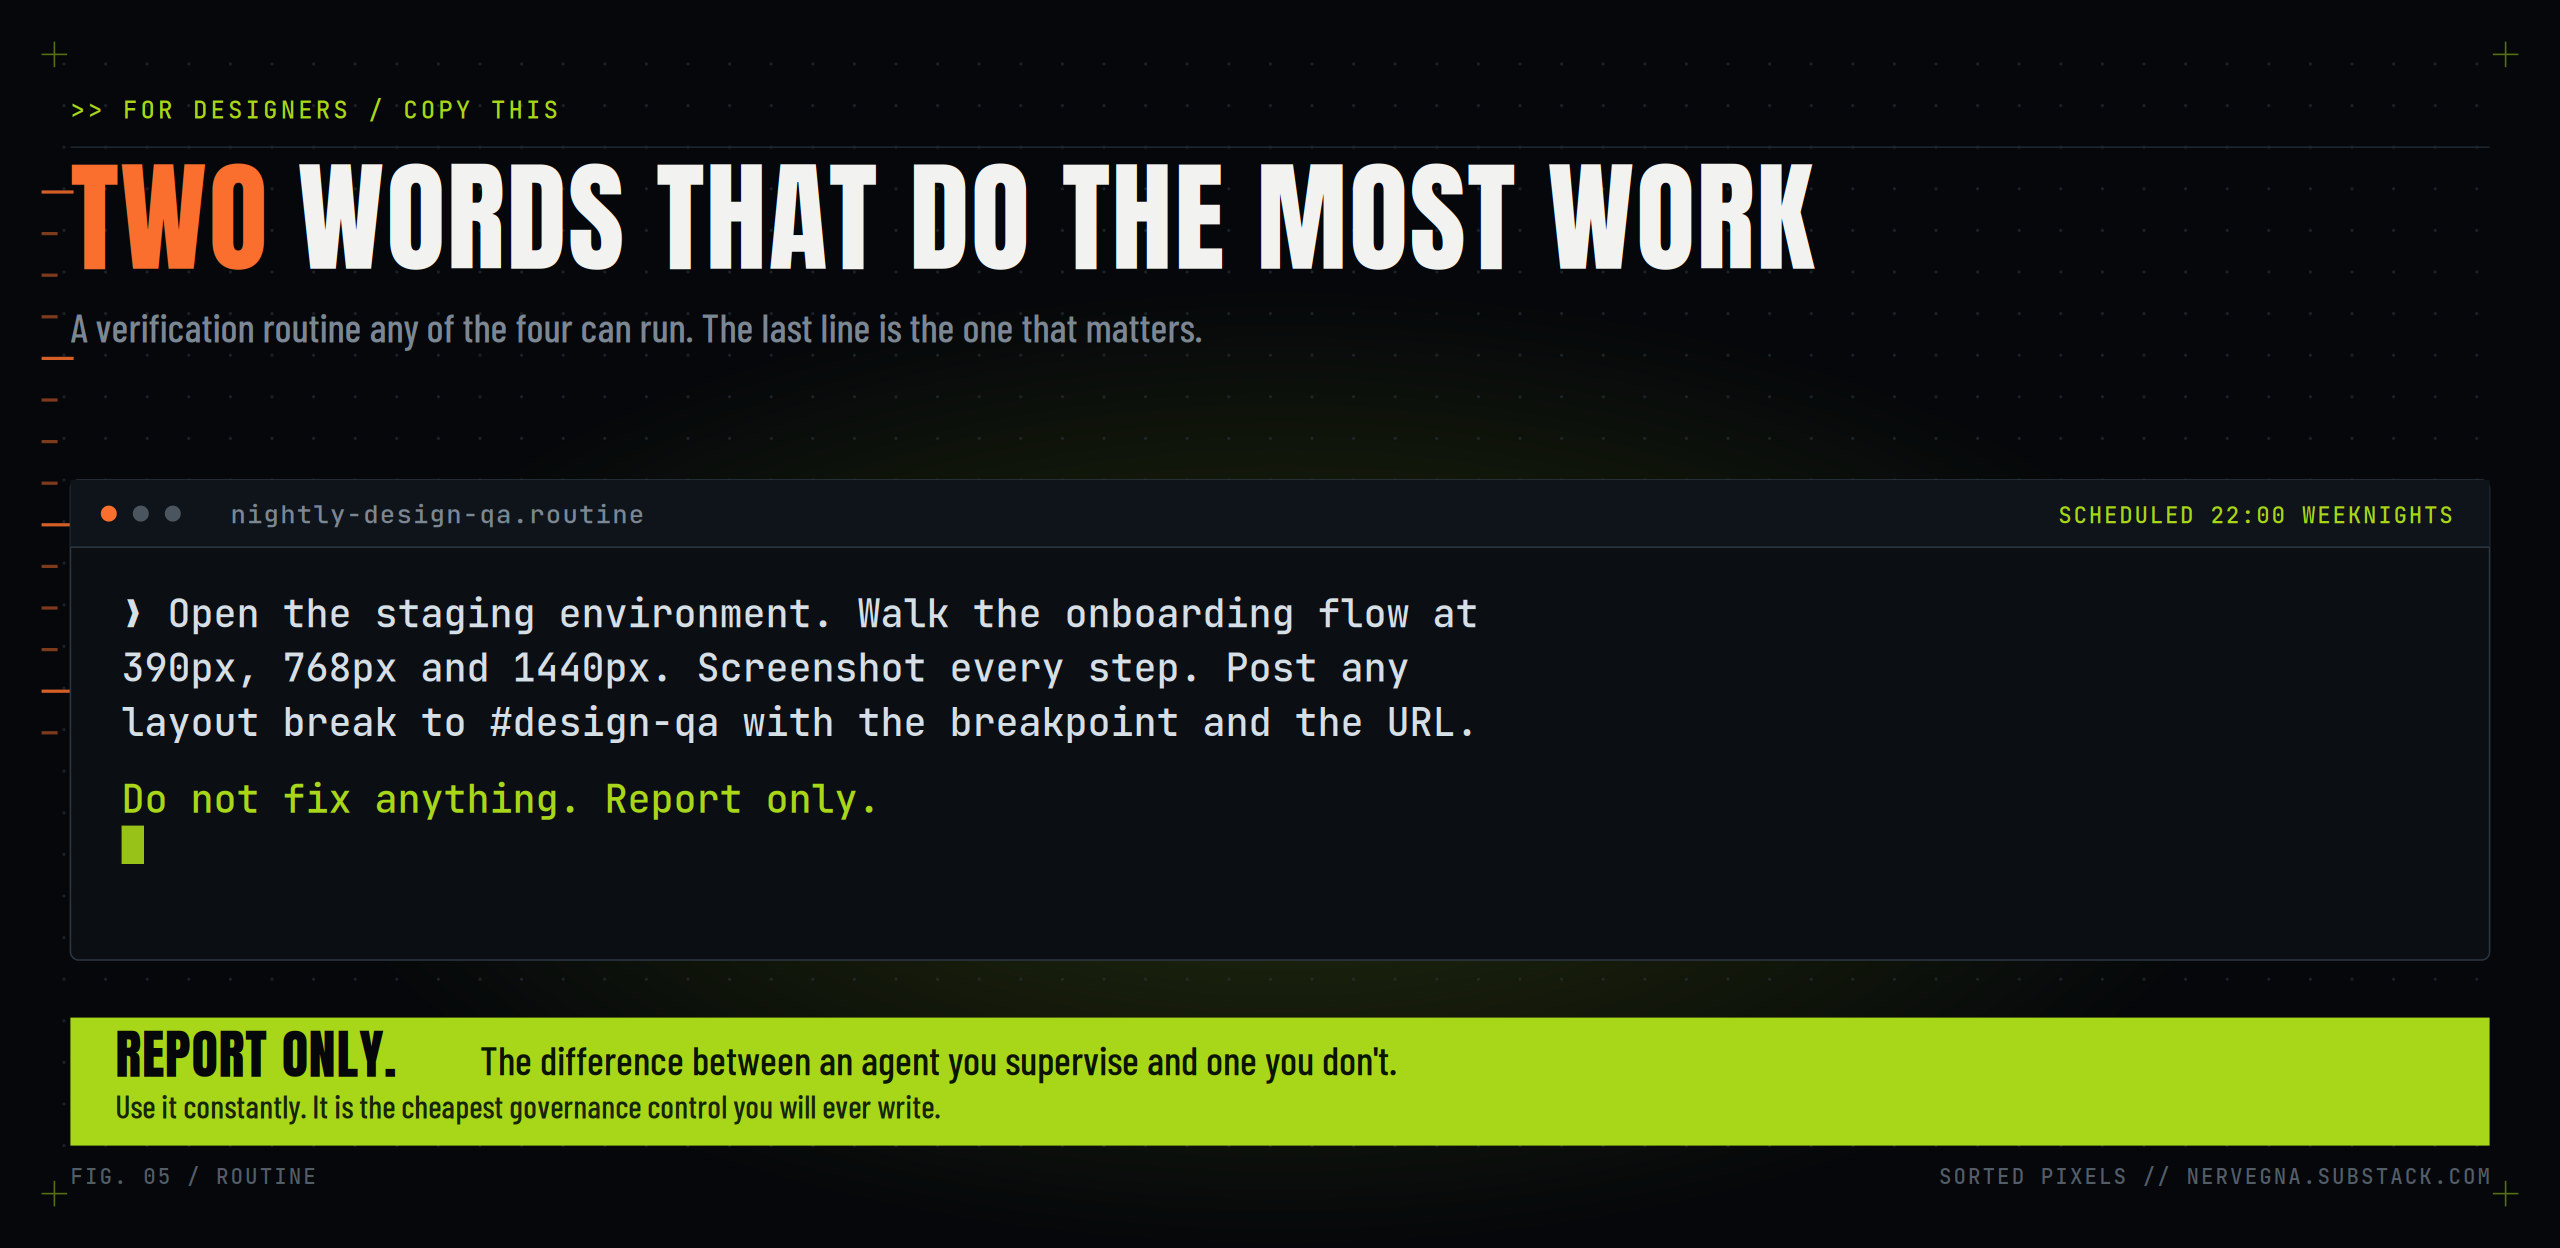
“Report only” is doing a lot of work in that prompt. Use it constantly.
What none of these four will do is decide whether the flow is any good. Agents have collapsed the boundary between design and development. They have not touched the boundary between doing and judging.
If you’re a PM
The obvious wins are real: action items pulled out of docs and calls into one list, a morning digest, competitive monitoring, a living feature-request list mined from Slack and support and tied back to actual customers.
The non-obvious cost is the thing I want you to plan for. Every agent you add creates an approval queue, and an approval queue is a backlog with worse ergonomics. Fifty routines per Bot is not a capacity, it’s a trap. Ten routines you read the output of beat fifty you rubber-stamp.
Before you scale anything, write down the answer to: how do I find out this agent has been quietly wrong for two weeks?
The rule that fixed this for me is worth stealing regardless of which product you land on. Every agent stays silent unless something is actually wrong. Most notifications are noise, and an agent that only pings you when it has something real to say is worth ten that send status updates. It sounds like a preference. It’s actually a governance control, because the moment your agents chatter, you stop reading them, and an unread agent is an unsupervised one.
If you’re a design or experience leader buying this
Three questions, in this order.
Custody. Whose machine, whose credentials, whose network. If the answer is “the vendor’s VM, holding a live session to my client’s tenant,” you have a procurement conversation, not a tooling conversation.
Continuity. Does it remember, and can you delete what it remembers? Grok Bot’s deletion story is incomplete by its own documentation.
Accountability. Can compliance pull a record without asking you nicely? Today that’s a real differentiator: Cowork session transcripts and metadata are available through the Compliance API for Enterprise as of 26 August. Grok Bot has a per-Bot chat transcript and no cross-team queryable view. On the self-hosted side you get whatever you build, which is honest, and which means you have to build it.
On 1 May 2026 six Five Eyes cyber agencies published joint guidance on adopting agentic AI: roughly 100 recommendations, 23 risks, and a headline that reads least privilege, system isolation, non-overridable guardrails. Grok Bot’s shared-session architecture is the deliberate opposite of that. I’m not calling that disqualifying. I’m saying it should be a decision somebody signed, not a default somebody inherited.
If you run CX or ops
This is where Grok Bot’s specific bet pays off hardest. Invoice collection across vendor portals. Expense reconciliation. Account-health watch lists. The systems that never got an API are exactly the systems eating your team’s week.
Pilot it on one workflow, in an isolated account, with a virtual card and a spend limit that exists outside the vendor’s product. Then measure.
The honest accounting
Things I would not let anyone gloss over.
The access story churned three times in sixteen days. Launch on 11 August, expansion announced only in an X post on 21 August, then “included with more plans” on 26 August. Cursor forum threads still show Pro users hitting upgrade prompts. The docs shipped ahead of the rollout.
The limit burn is the single most-documented complaint. xAI acknowledged it publicly on 24 August and said efficiency improvements were coming. Combine an unpublished weekly allowance, no spend cap, no model picker, and billing that follows whichever model happened to serve you, and you have a product you should not deploy team-wide before you’ve watched one person’s spend for a full week.
The audit gap is architectural, not cosmetic. Actions run under your identity. The far-end log names you, not the Bot.
Prompt injection is a category problem, not a Grok problem. Grok chat has documented incidents, including Adversa AI’s cryptographic context injection work against Grok 4.5 Fast on grok.com, roughly 40% success across about 20 attempts, reported in June and still reproducible in August. That’s the chat product, not the Bot. But two 2026 papers make the point that matters for every product and harness on this list: persistent agentic memory can turn a one-time injection into a persistent compromise, and per-session prompt filtering isn’t sufficient defence for an agent that evolves its own memory. Hermes and Cowork have durable memory too. So does OpenClaw. Nobody gets to sit this one out. Anthropic at least publishes the threat model and warns about browser agents explicitly. Grok Bot’s materials don’t publish an equivalent.
And the launch-week success stories are self-selected. Seven curated wins with no denominator is marketing, not evidence. The launch post’s own admission that the Bot skipped some newsletters during an unsubscribe task is worth more than all seven.
What I’d actually run
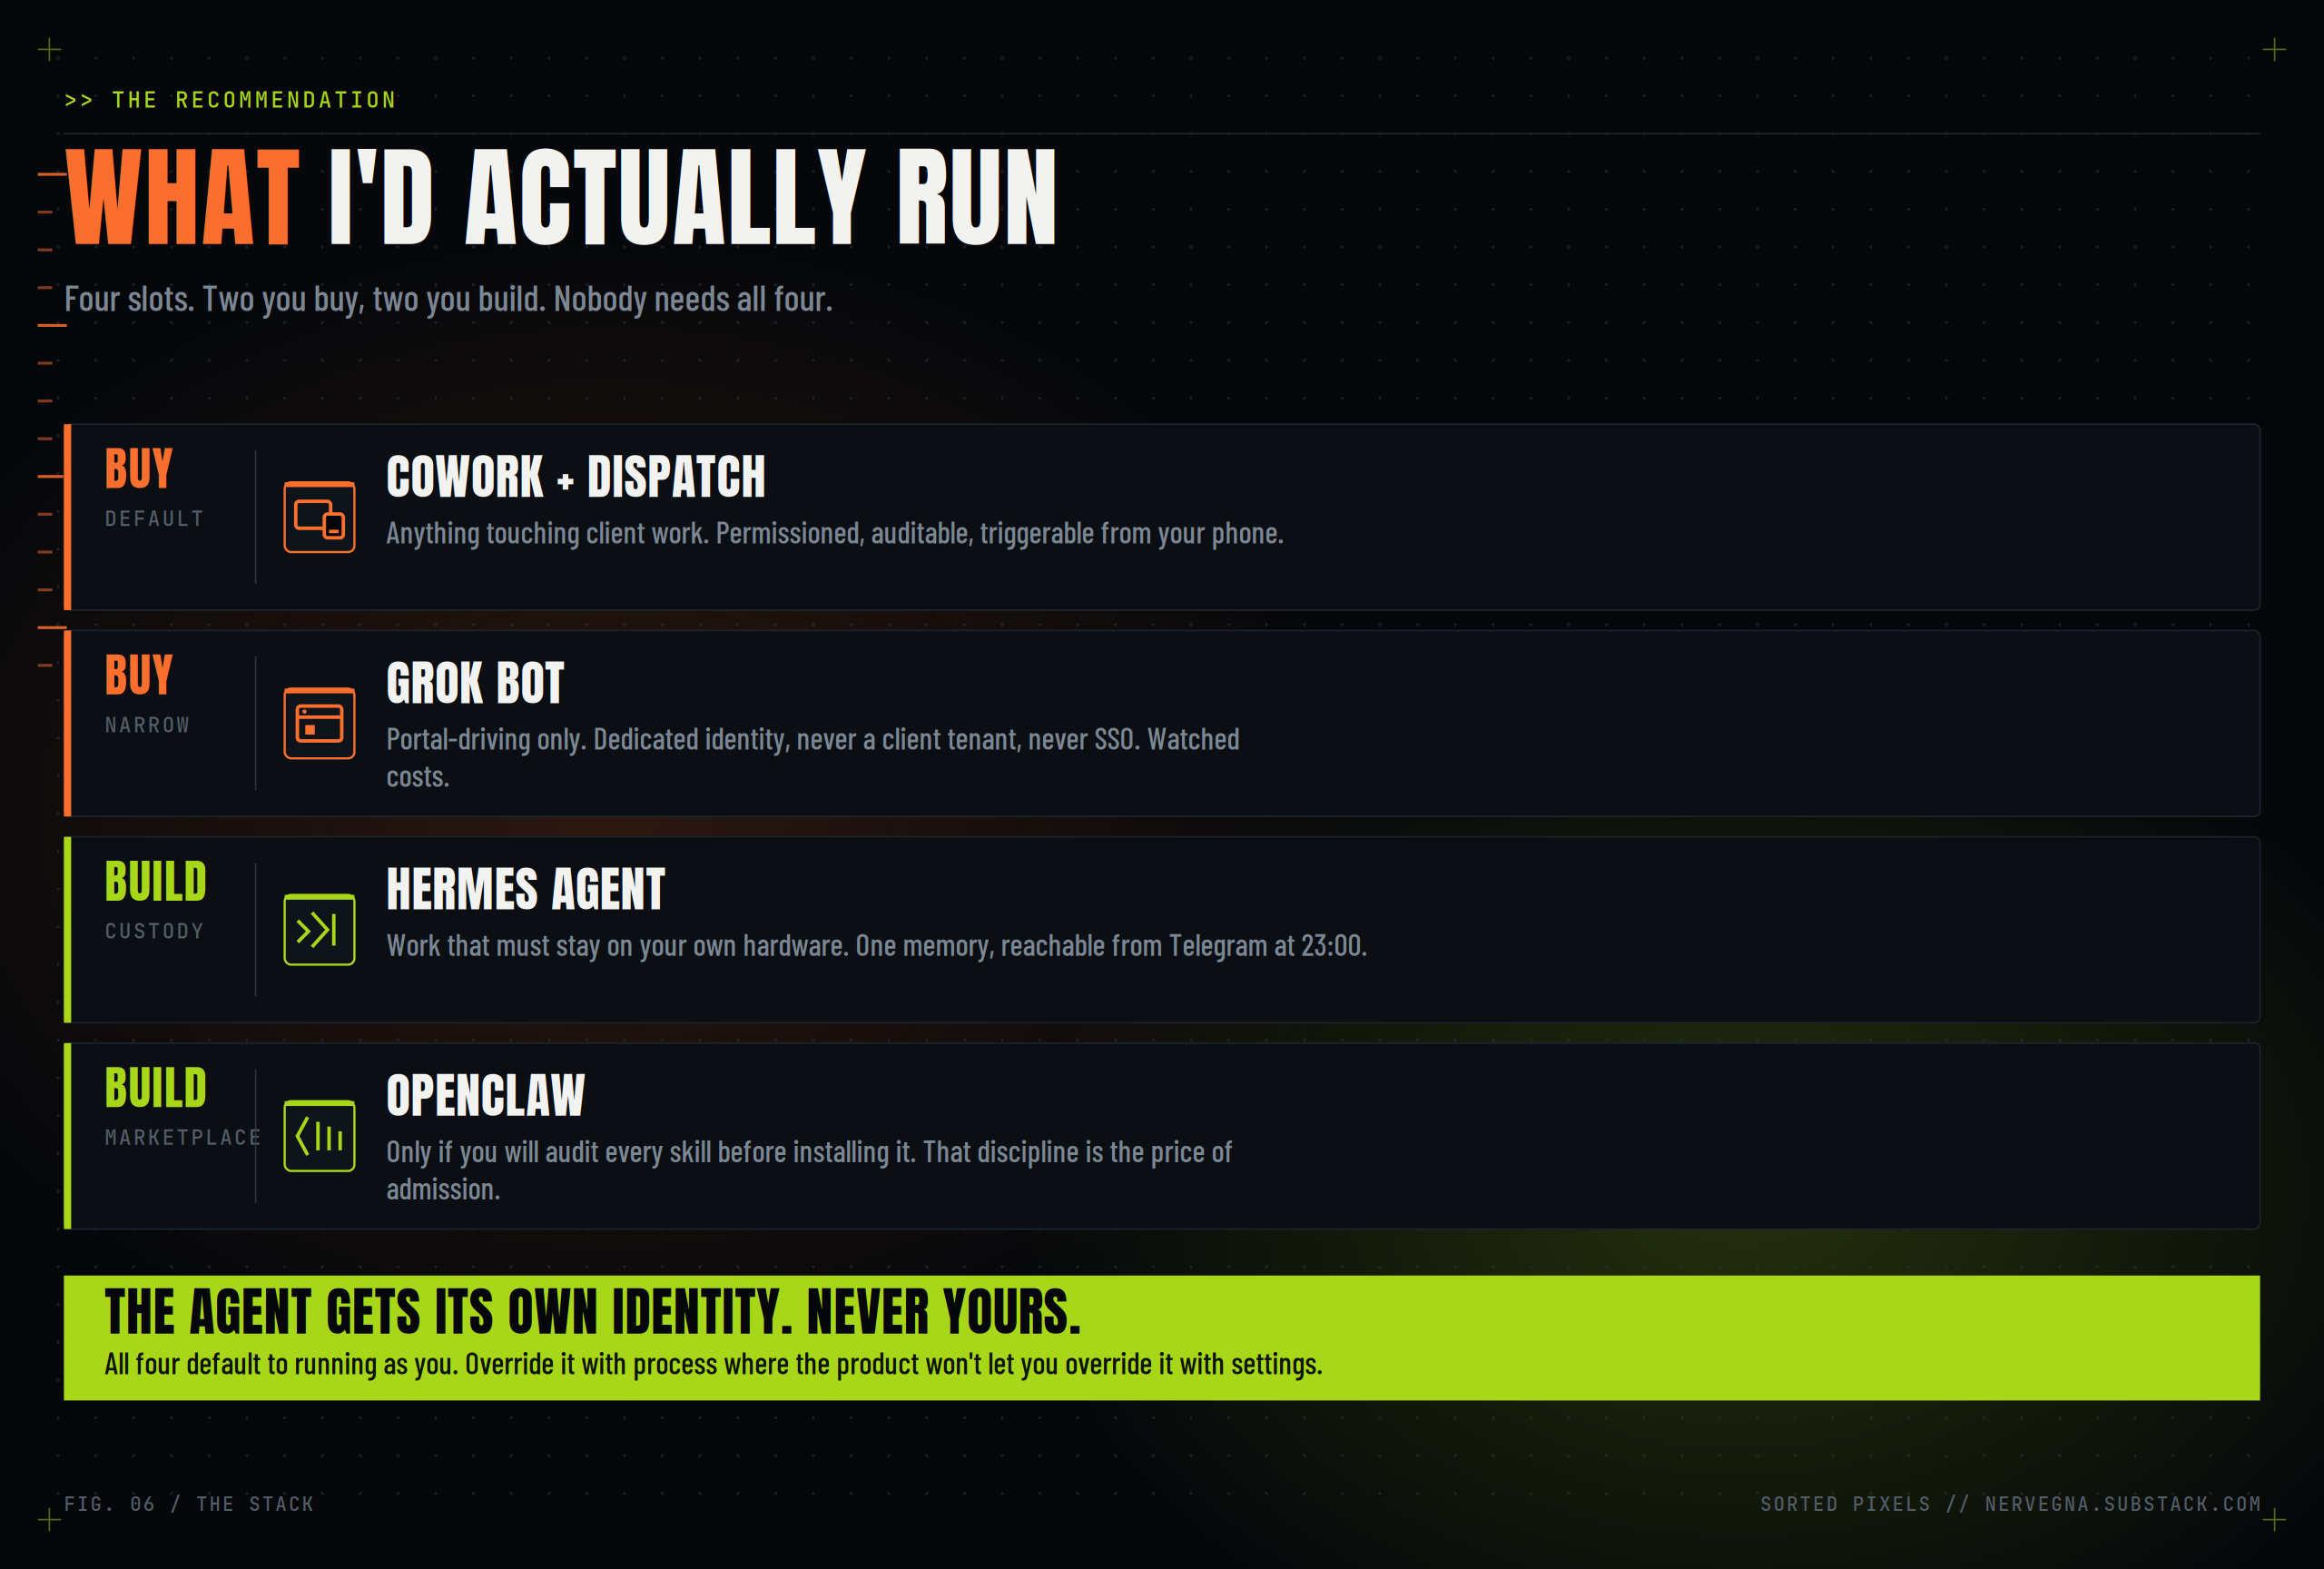
If you want the short version:
Buy, for anything touching client work: Cowork plus Dispatch is the default. Permissioned, auditable, and triggerable from your phone, which is where half of my real triggers happen anyway.
Buy, narrowly: Grok Bot for portal-driving, in a dedicated identity, never linked to a client tenant, never with SSO. One workflow. Watched costs. It earns its keep on the systems that have no API and never will.
Build, if you can staff it: Hermes where custody is non-negotiable or the work must live entirely on your own hardware, and where you want one memory reachable from Telegram at 23:00. OpenClaw if you want the marketplace and you have the discipline to audit every skill before you install it. That discipline is the price of admission on a harness, not an optional extra, and “we’ll do it later” is how the February vulnerability list happened to other people.
The honest test for the build column: name the person who owns it. I can name mine. It’s me, and it’s a Mac mini that has been running since February, and the maintenance is real and ongoing. Prompts need tuning. Agents hallucinate things you have to catch. The overnight pipeline sometimes produces drafts I’d never publish. That’s the actual cost of the right-hand side of the chart, and I’d still take it for the work that has to stay on my own hardware.
If you can’t name that person, you’re buying. You just haven’t admitted it yet.
And one rule underneath all four: the agent gets its own identity, never yours. Every one of these currently defaults to running as you. That’s a design decision you’re allowed to override with process even when the product won’t let you override it with settings.
The thing worth sitting with
Everyone is asking which agent is best. That’s the wrong question and it has a boring answer, which is that they converge in about six months.
The question that survives is smaller and much less fun: which of these are you willing to be personally accountable for?
Because that’s what “it logs in as you” actually means. Not convenience. Liability. The most sophisticated orchestration you build this year will be judged on a single failure that names you in someone else’s audit log.
Design the accountability before you design the automation. That part has never been delegable, and none of these four is offering to take it.